Running Kubernetes on GPU infrastructure usually means assembling several layers before a workload can start. Teams need to secure GPU capacity, provision a control plane, bring worker nodes online, install core cluster components and add-ons, validate cluster health, and establish access.
Today, Hyperbolic is introducing Managed Kubernetes, now available in beta for On-Demand GPU infrastructure in select regions. From the Hyperbolic console, teams can go from bare metal to a ready-to-use GPU Kubernetes cluster in one workflow.
What Managed Kubernetes changes
Hyperbolic already offers self-serve access to on-demand GPU infrastructure. Managed Kubernetes adds an orchestration layer for teams running containerized training, fine-tuning, inference, evaluation, and other GPU workloads. Instead of assembling the control plane, GPU workers, cluster services, and access path separately, teams can create the environment through one product flow.
The cluster runs on the same GPU infrastructure provisioned through Forge, Hyperbolic's infrastructure layer for turning GPU capacity into ready-to-use compute. Managed Kubernetes builds on that foundation by provisioning the control plane, joining GPU workers, handling networking, applying the selected cluster components, and exposing a standard access path.
Once the cluster is ready, teams can use standard Kubernetes tooling to deploy and manage their workloads and configurations.
What is available today
Self-serve cluster creation: Create a managed GPU Kubernetes cluster end to end from the Hyperbolic console.
Hosted control plane: Hyperbolic runs and maintains a three-replica Kubernetes control plane, so your team does not need to provision or manage etcd or control-plane nodes.
GPU worker nodes: Select the GPU capacity and worker count for your workloads. Your newly provisioned GPU instances join the cluster as worker nodes. Worker count is set at launch; in-place scaling is not supported in the beta.
GPU-ready add-ons: GPU drivers and GPU and networking add-ons, including the NVIDIA GPU Operator and NVIDIA Network Operator, are installed at bootstrap so pods can request nvidia.com/gpu capacity. Required add-ons are always included, and optional add-ons are selected during setup.
Cluster health and GPU metrics: Track provisioning progress, monitor overall cluster health, and view GPU utilization across worker nodes from the dashboard.
Download kubeconfig and connect: Download the cluster-admin kubeconfig file and use it with kubectl or other Kubernetes-compatible tools to communicate with the cluster API.
GPU instance pricing and billing
GPU workers use the same hardware, interconnect, and hourly rates as renting the underlying instances directly. Cluster nodes appear in billing history under the cluster name, alongside your other rentals. Review the full cluster configuration and estimated total hourly cost before launching.
How to launch, connect to, and monitor a GPU Kubernetes cluster
Start with the three setup stages in the console: GPUs, Workload, and Set-up & Launch. Then follow the cluster through provisioning, connect with kubectl, and inspect GPU activity. The screenshots show several demo clusters, not one continuous deployment, so names, GPU types, and node counts vary. Example regions, versions, prices, and status values are illustrative; use the values shown in your console.
1. Open Kubernetes
Sign in to the Hyperbolic console, select Kubernetes in the main navigation. The New cluster page opens and you can choose your GPU capacity.
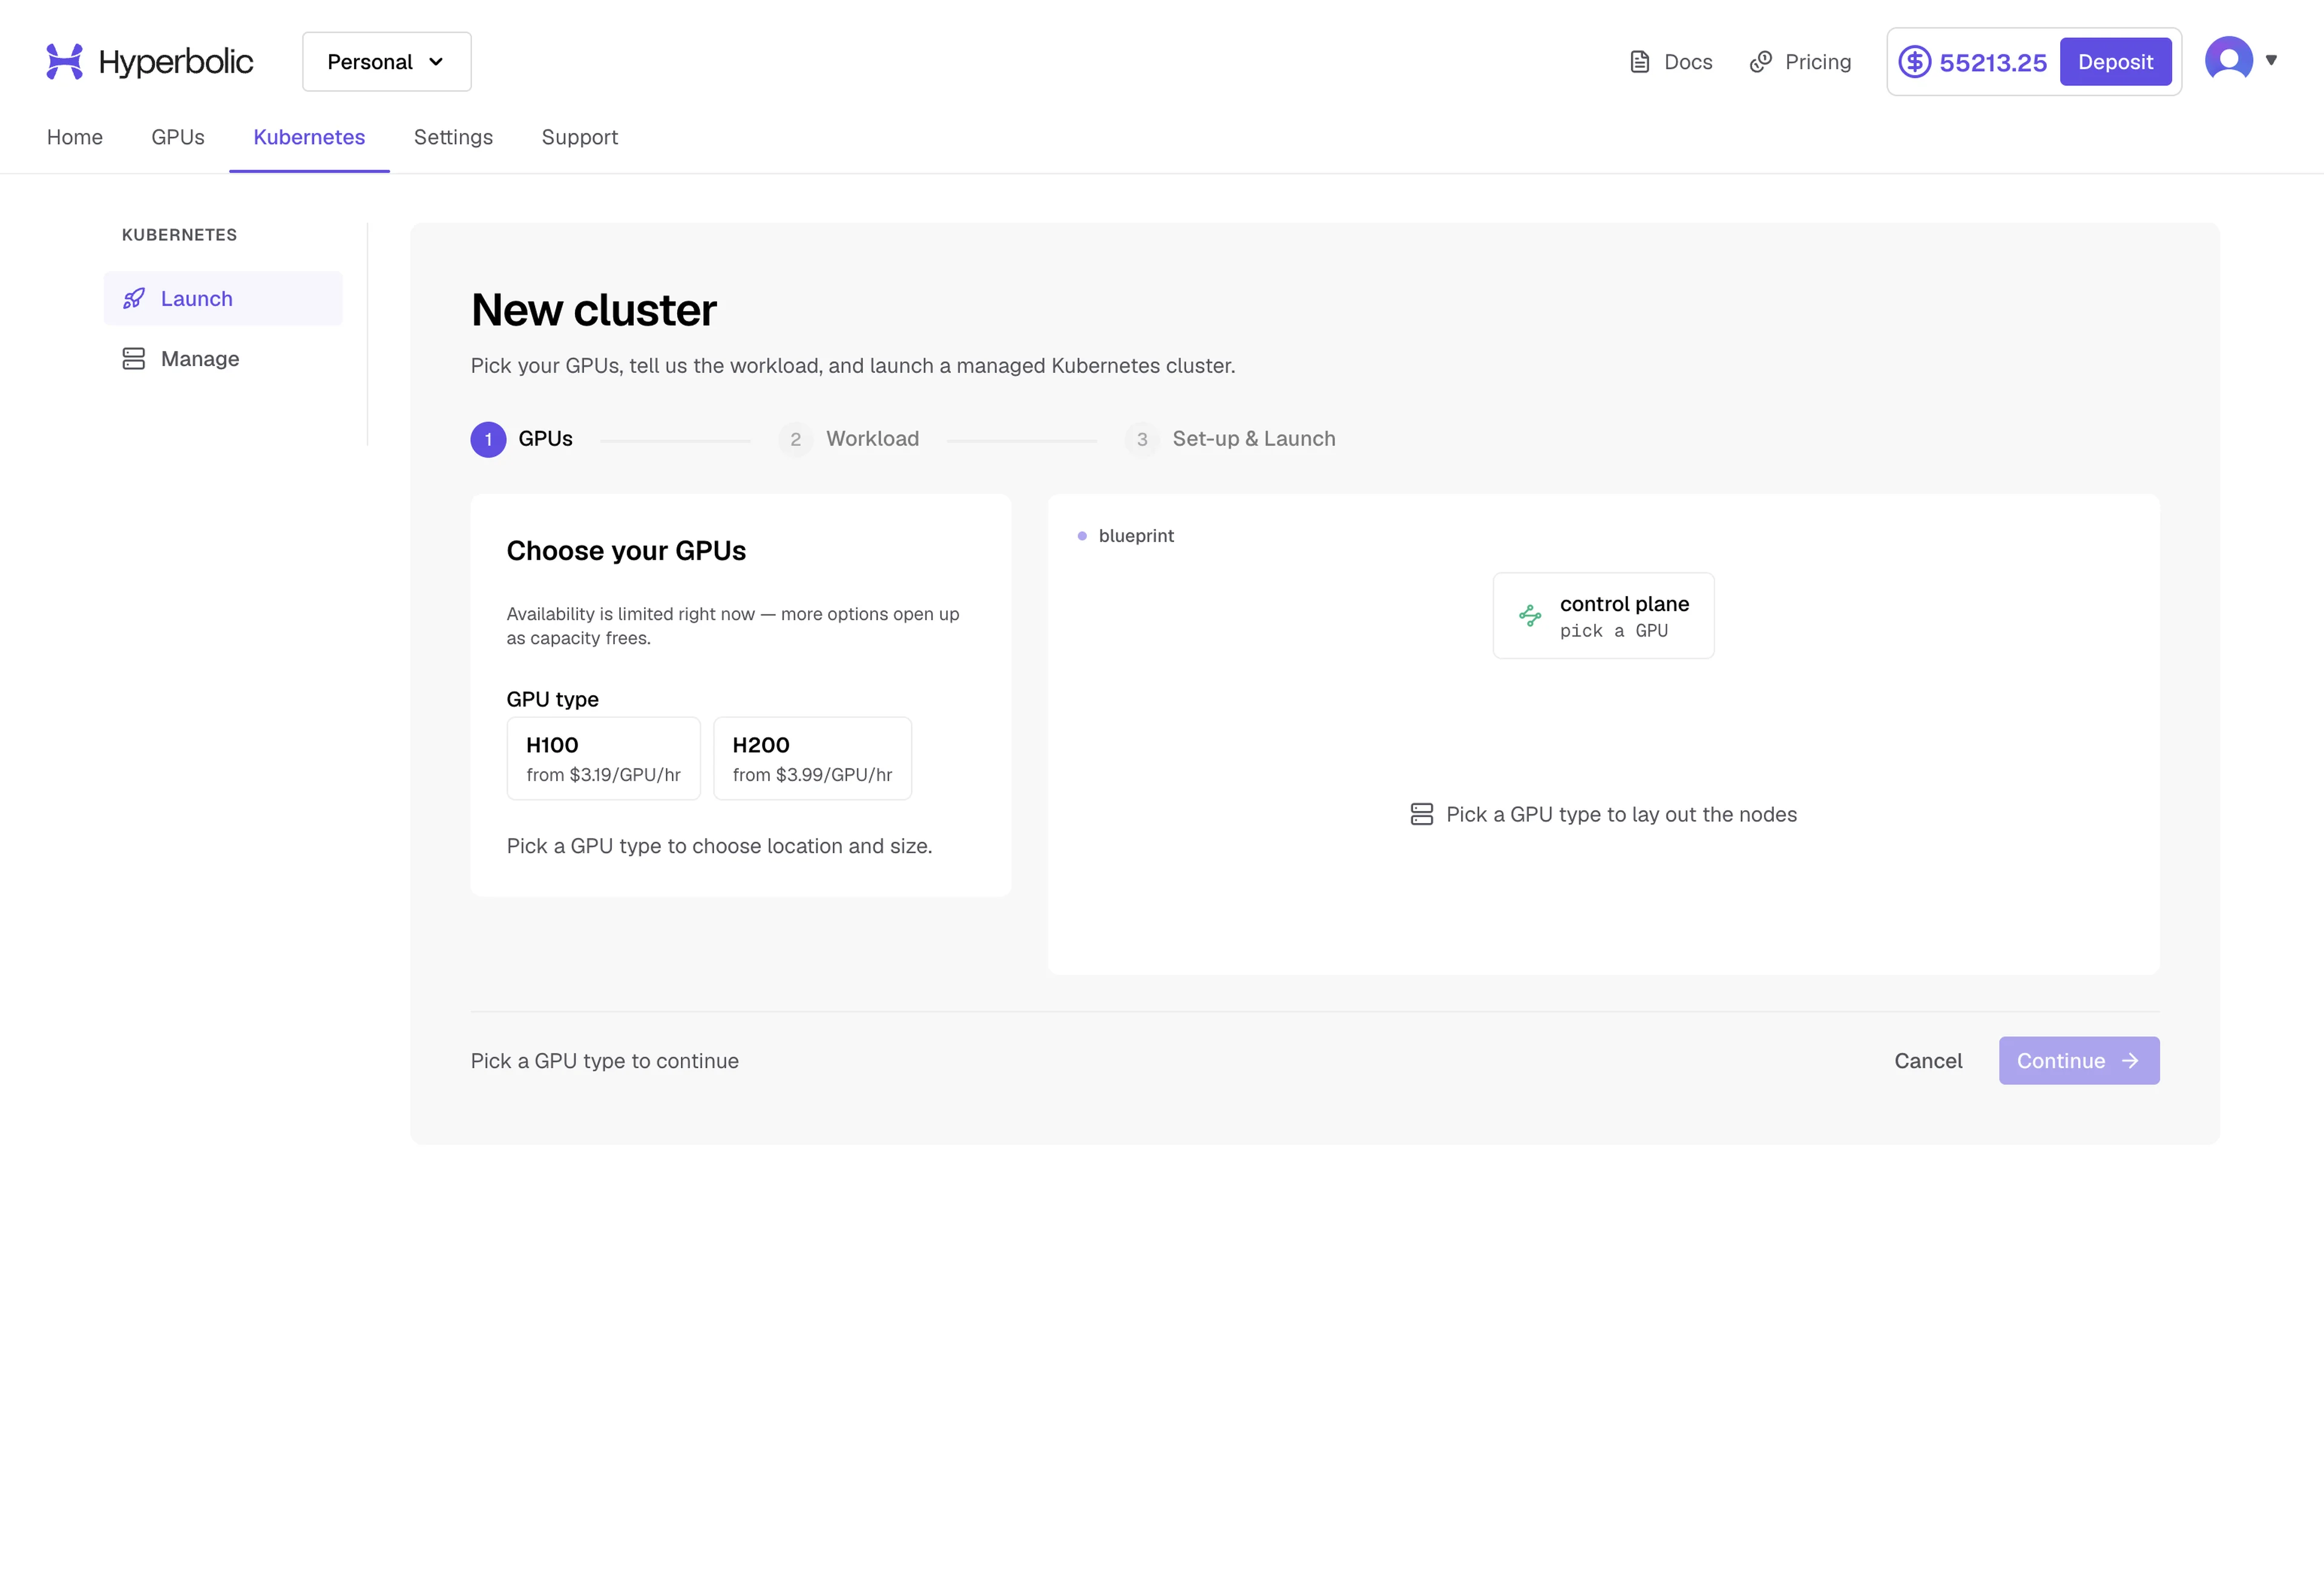
Open Kubernetes from the main console navigation.
2. Select GPU capacity
Choose the available GPU type, location, and number of worker nodes. The blueprint updates to show the control plane, GPU workers, total GPU count, and estimated hourly rate. Confirm that the capacity and cost match your requirements, then select Continue.
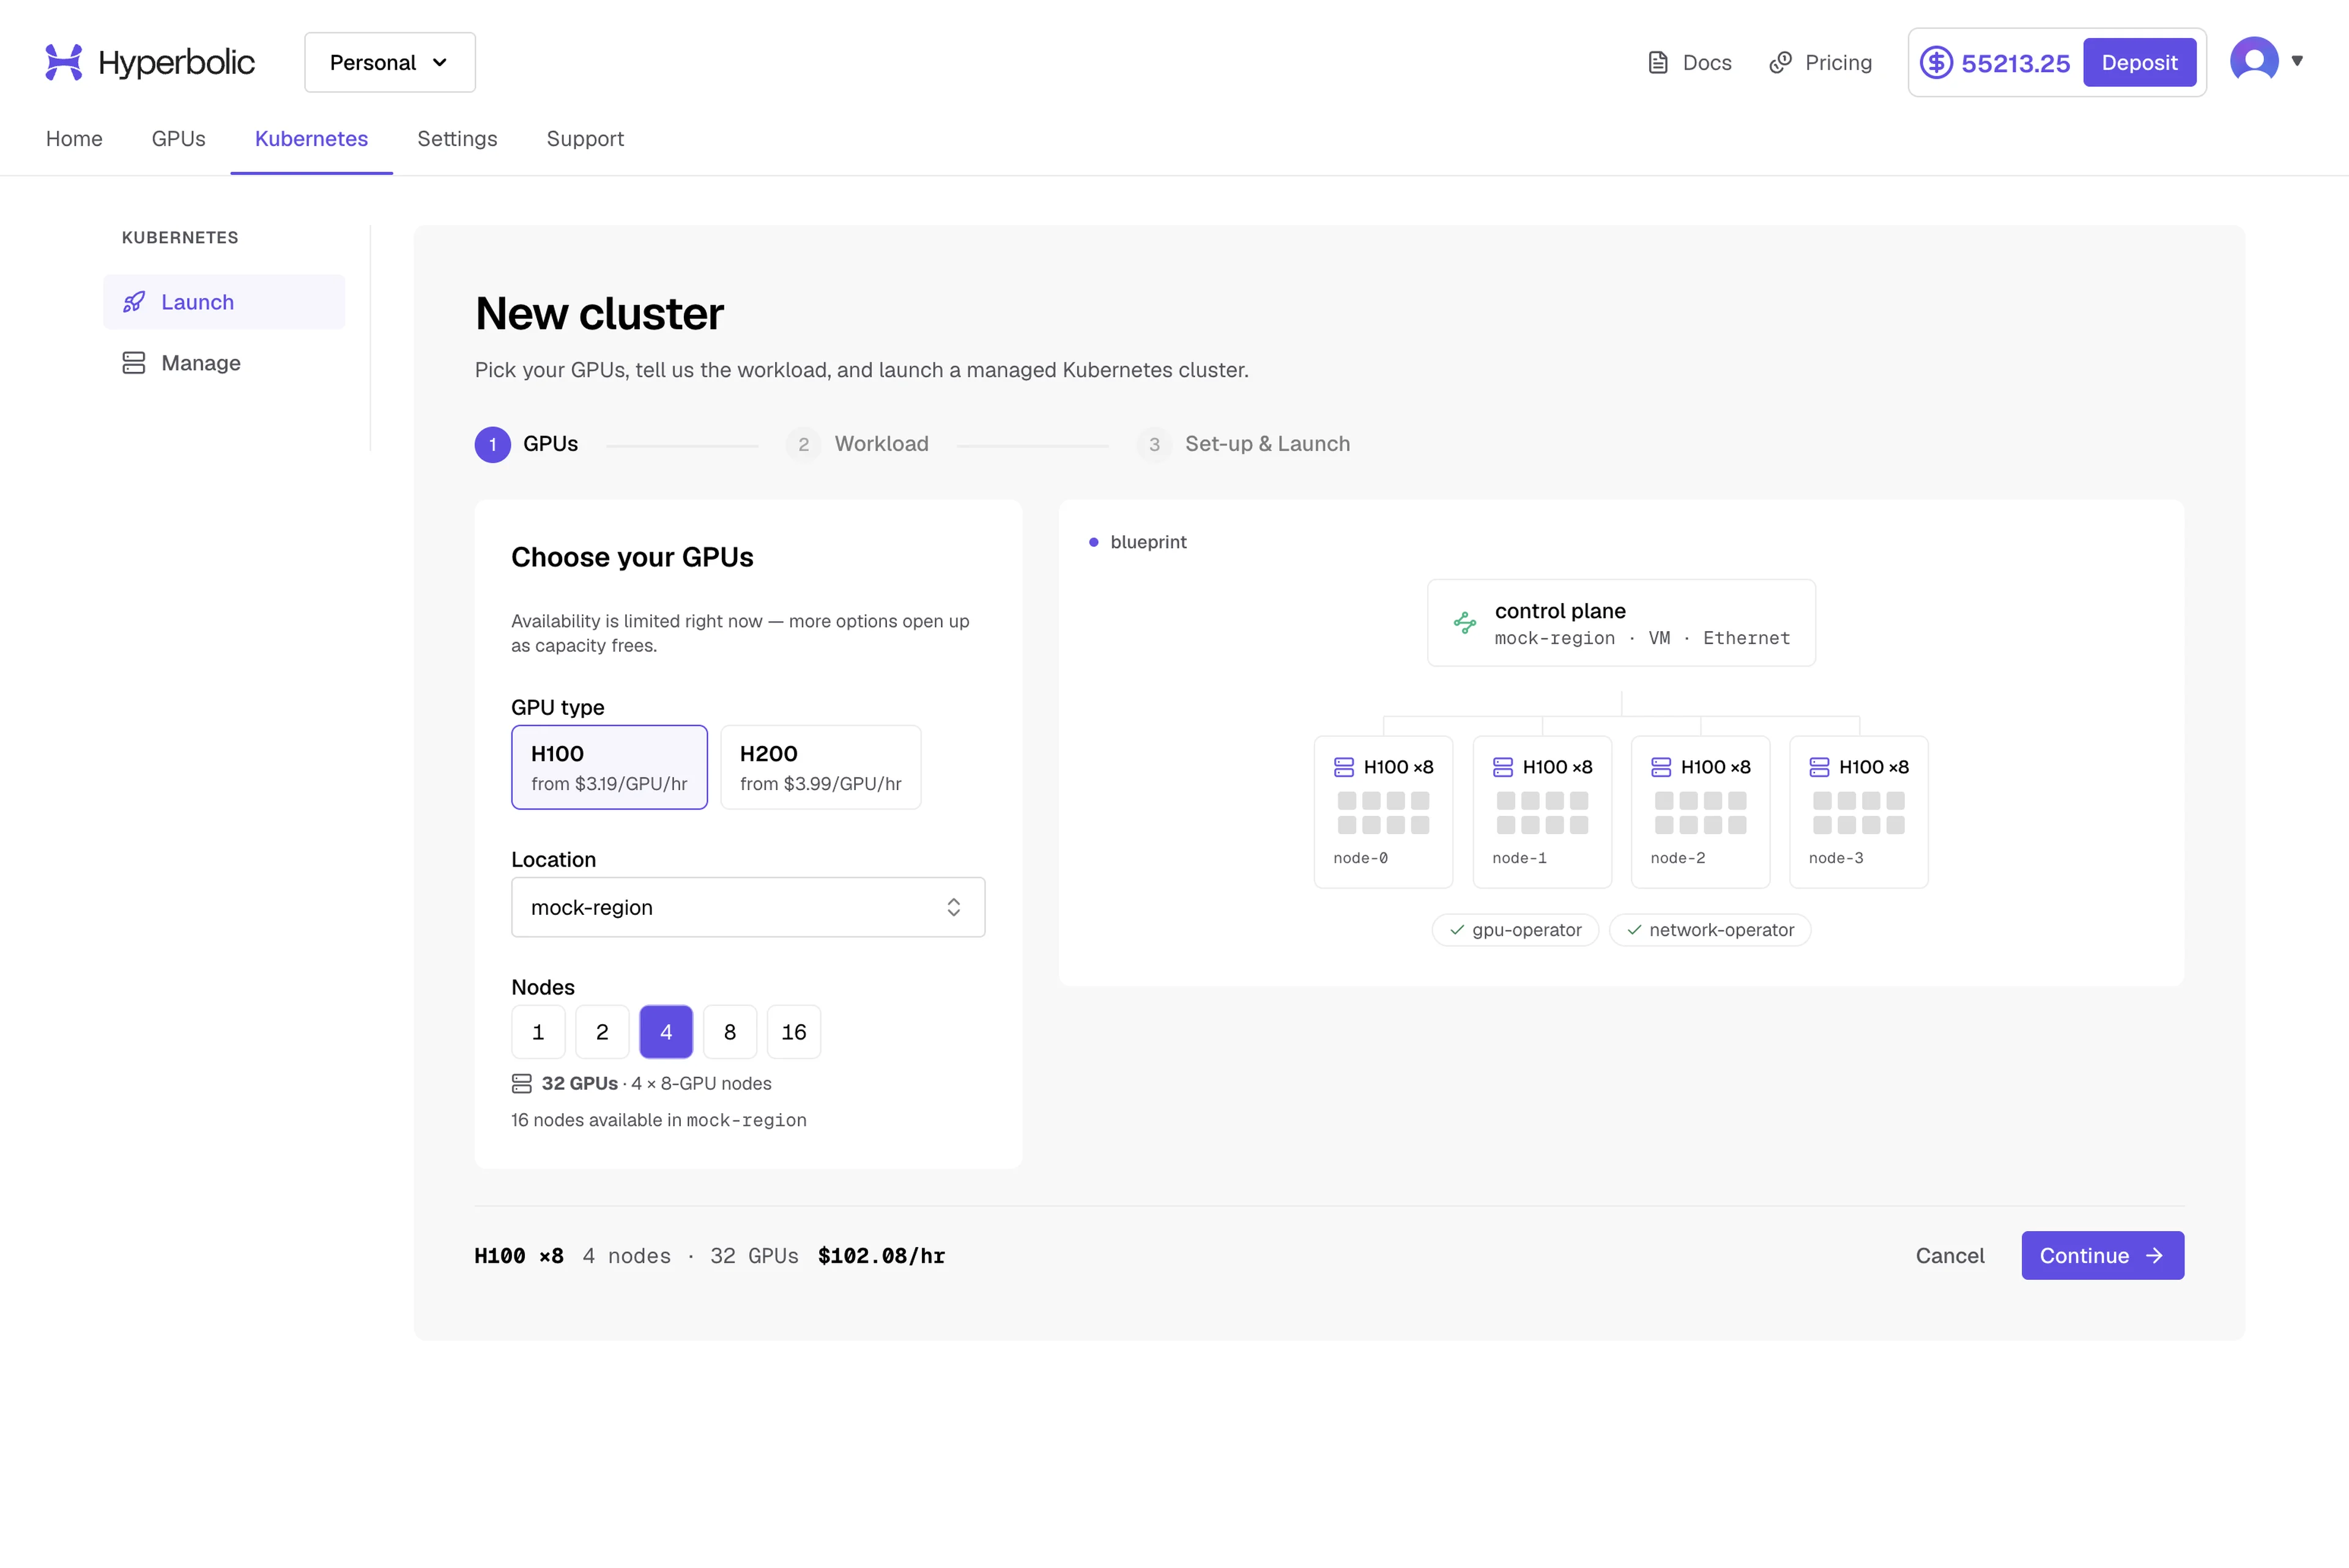
Select the GPU type, region, and worker-node count, then review the blueprint and estimated hourly rate.
3. Choose the workload
On the Workload stage, select Distributed training, Fine-tuning, Inference & serving, Notebooks & dev, or Custom. The choice suggests storage defaults; it does not deploy your application. Select Continue to open Set-up & Launch, where you can review the configuration before creating the cluster.
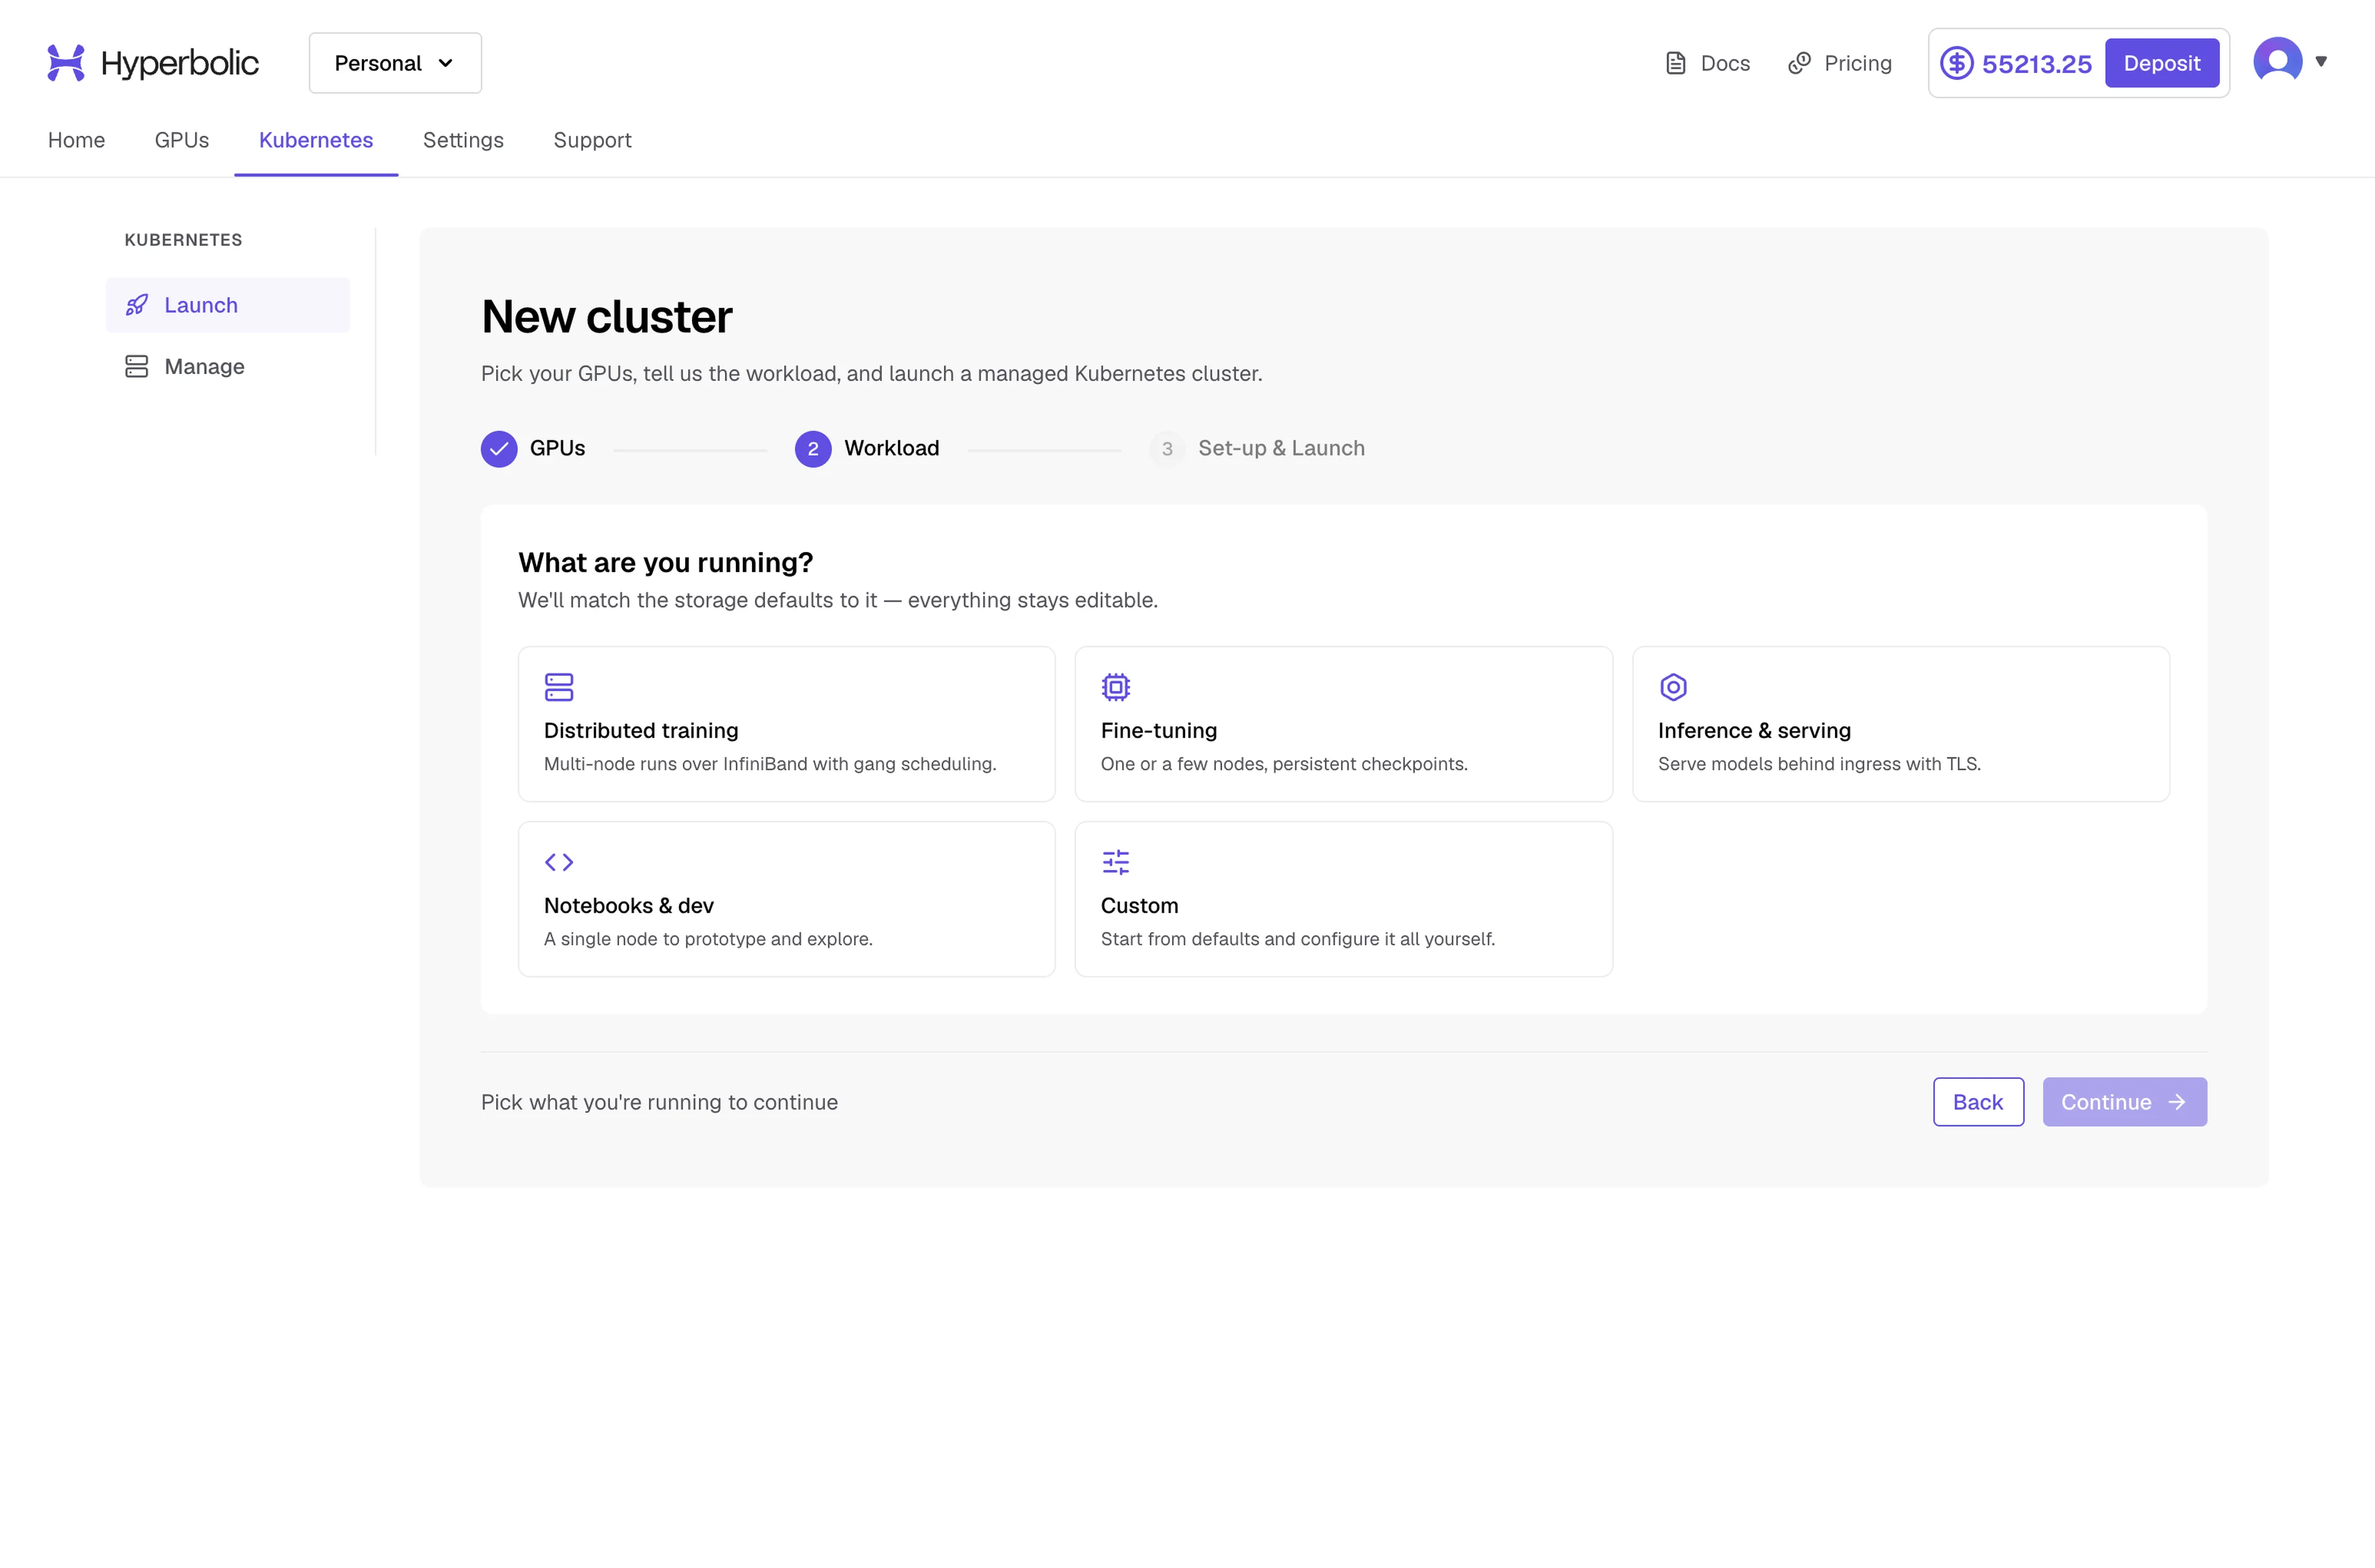
Choose a workload profile after selecting GPU capacity.
4. Configure and launch
On Set-up & Launch, enter a cluster name and review the Kubernetes version, storage configuration, required and optional add-ons, and networking defaults. Check the Order Summary against your intended GPU type, node count, region, and total hourly cost. Use Back if you need to revise earlier choices. Select Launch cluster to begin provisioning, then open Manage to find the new cluster.
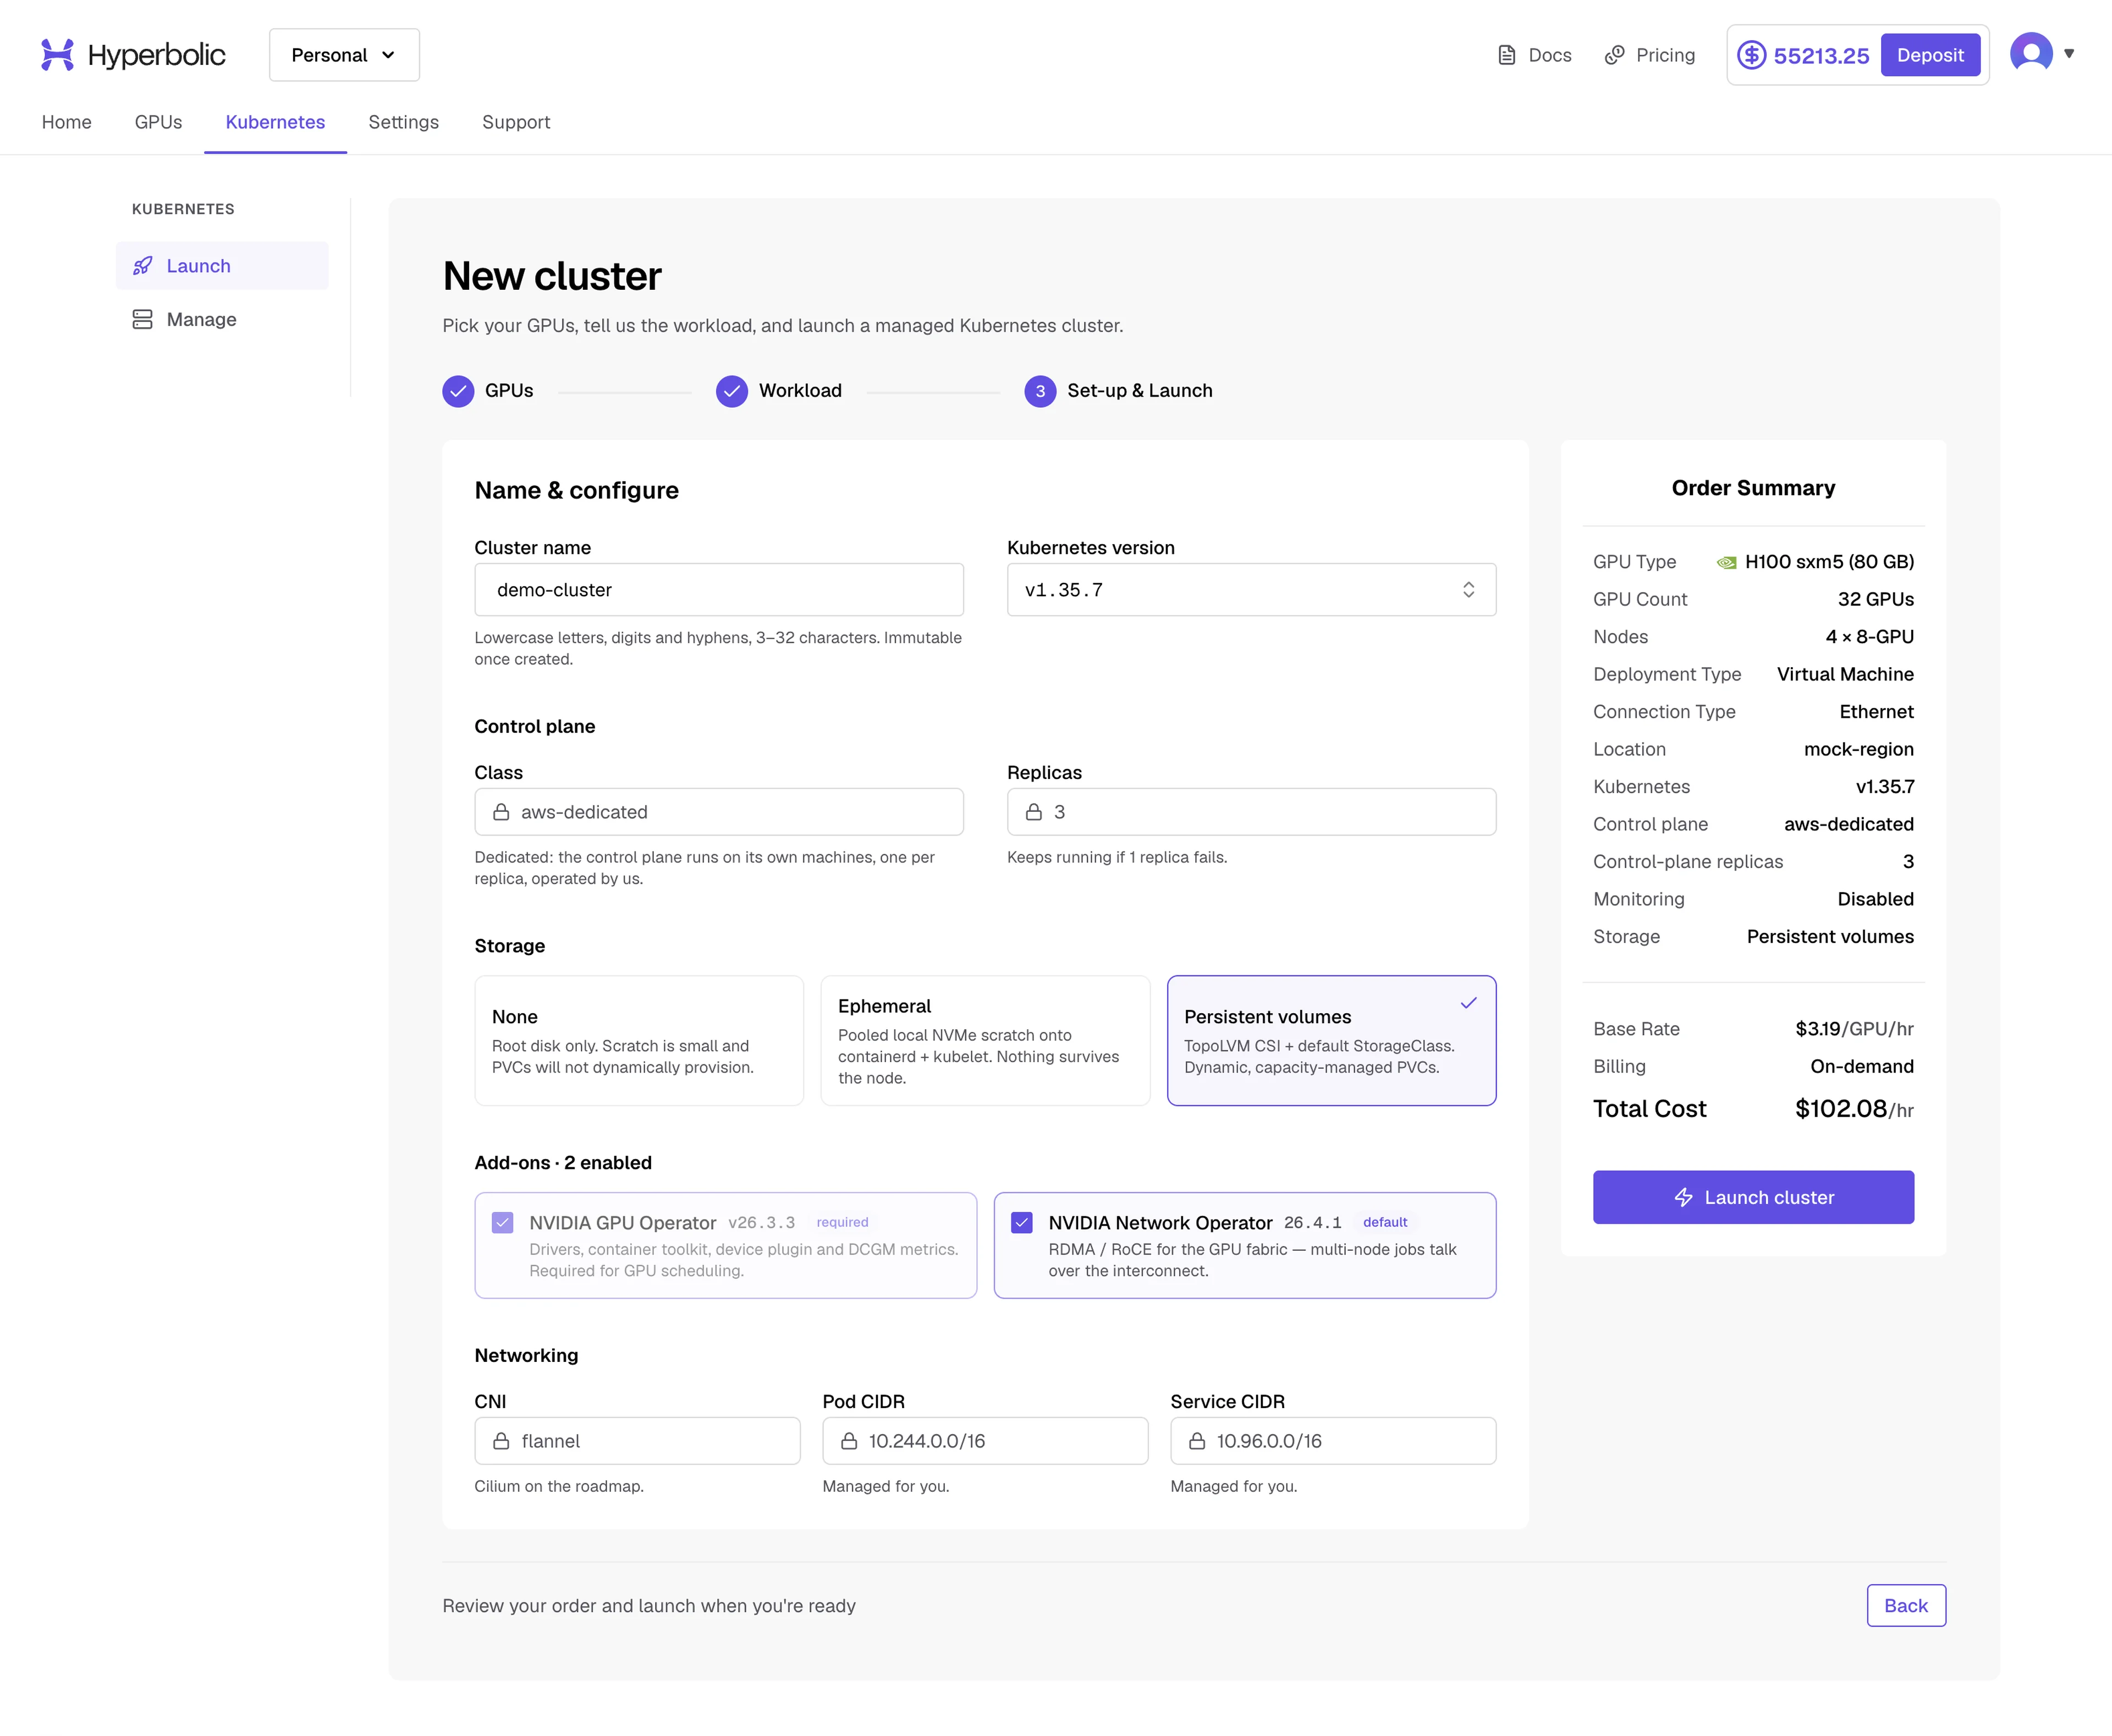
Confirm the final configuration and cost before selecting Launch cluster.
5. Find your cluster in Manage
Open Manage in the Kubernetes sidebar. This fleet view lists your clusters, their status, and their node and GPU counts. Find the cluster name you entered during setup and select View details on its row to open the provisioning view.
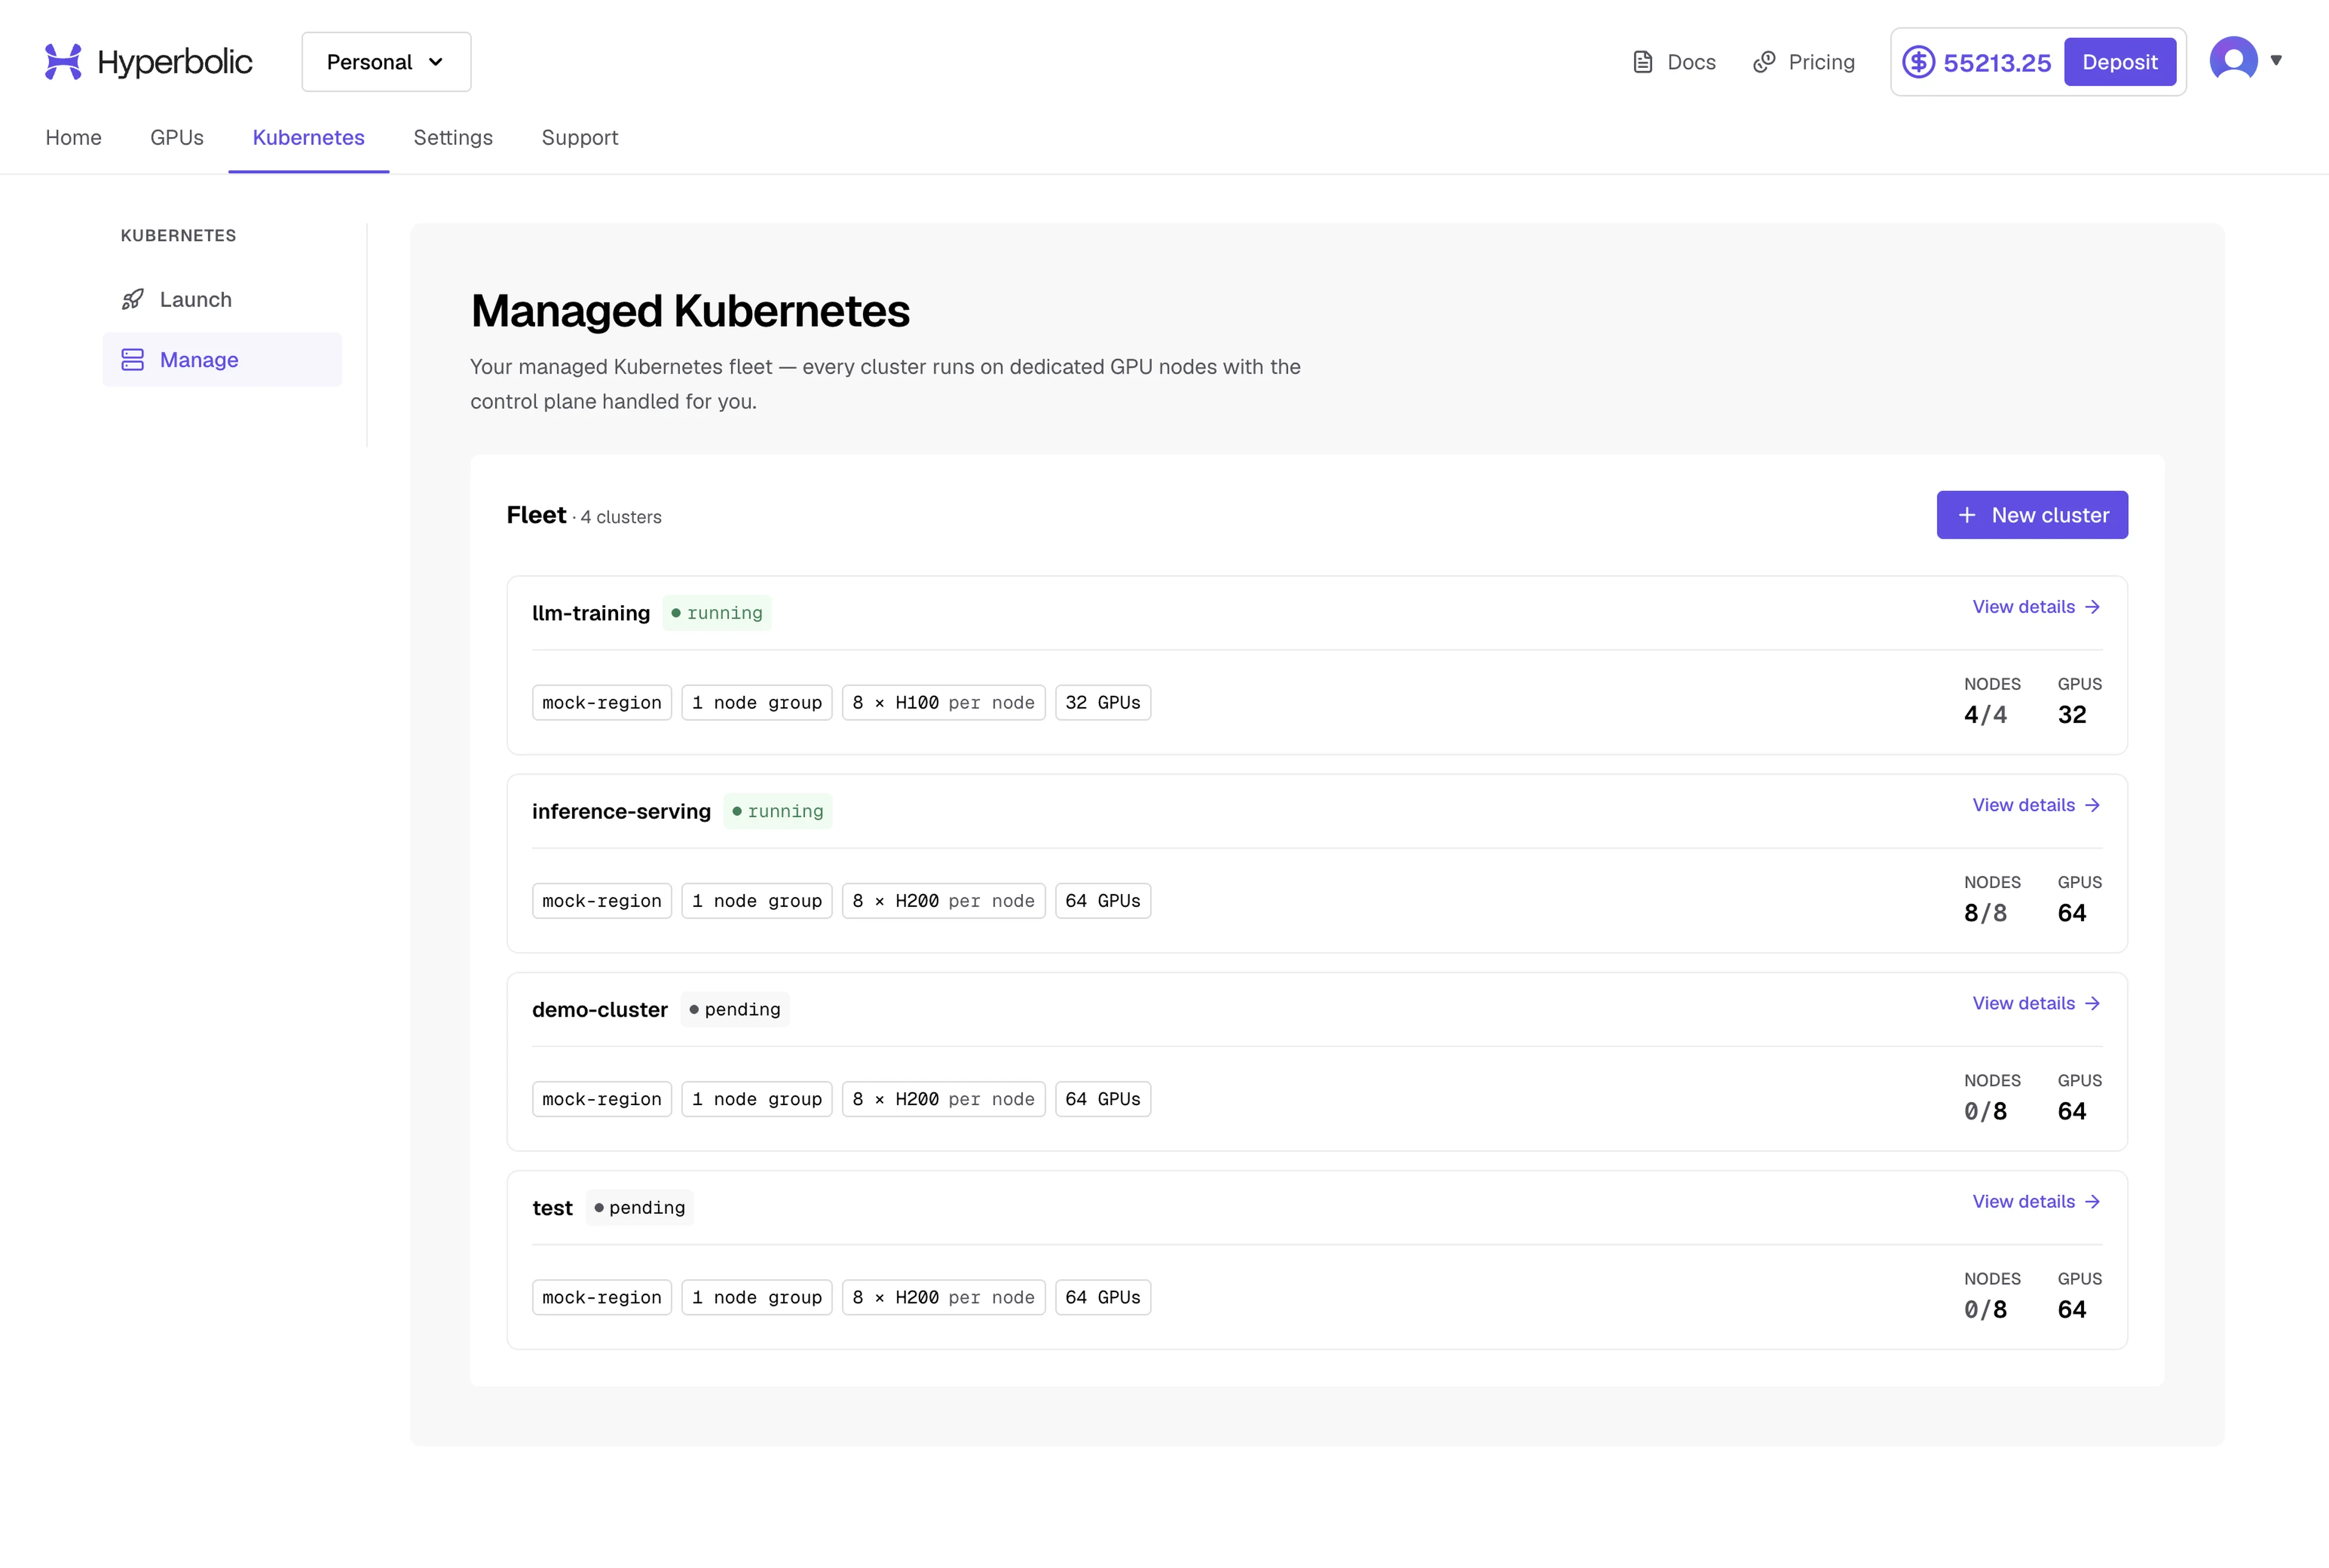
Find your cluster in Manage and select View details to follow its setup progress.
6. Track cluster provisioning
The cluster's Overview tab shows bring-up progress, a topology diagram, and recent activity while Hyperbolic prepares the environment. These are automatic infrastructure steps; you do not need to provision the control plane or join workers yourself.
Confirm capacity. Hyperbolic confirms that the GPU instances selected during configuration are still available when the request begins.
Provision the control plane. The platform creates a highly available Kubernetes control plane managed by Hyperbolic.
Bring GPU workers online. Hyperbolic waits for the requested GPU nodes to finish provisioning, then joins them to the cluster as workers.
Apply cluster add-ons. The platform provisions GPU drivers and installs baseline services, required GPU and networking add-ons, and the optional add-ons selected during creation.
Validate health. Hyperbolic checks the environment and marks the cluster ready when the control plane, worker nodes, and required components are healthy.
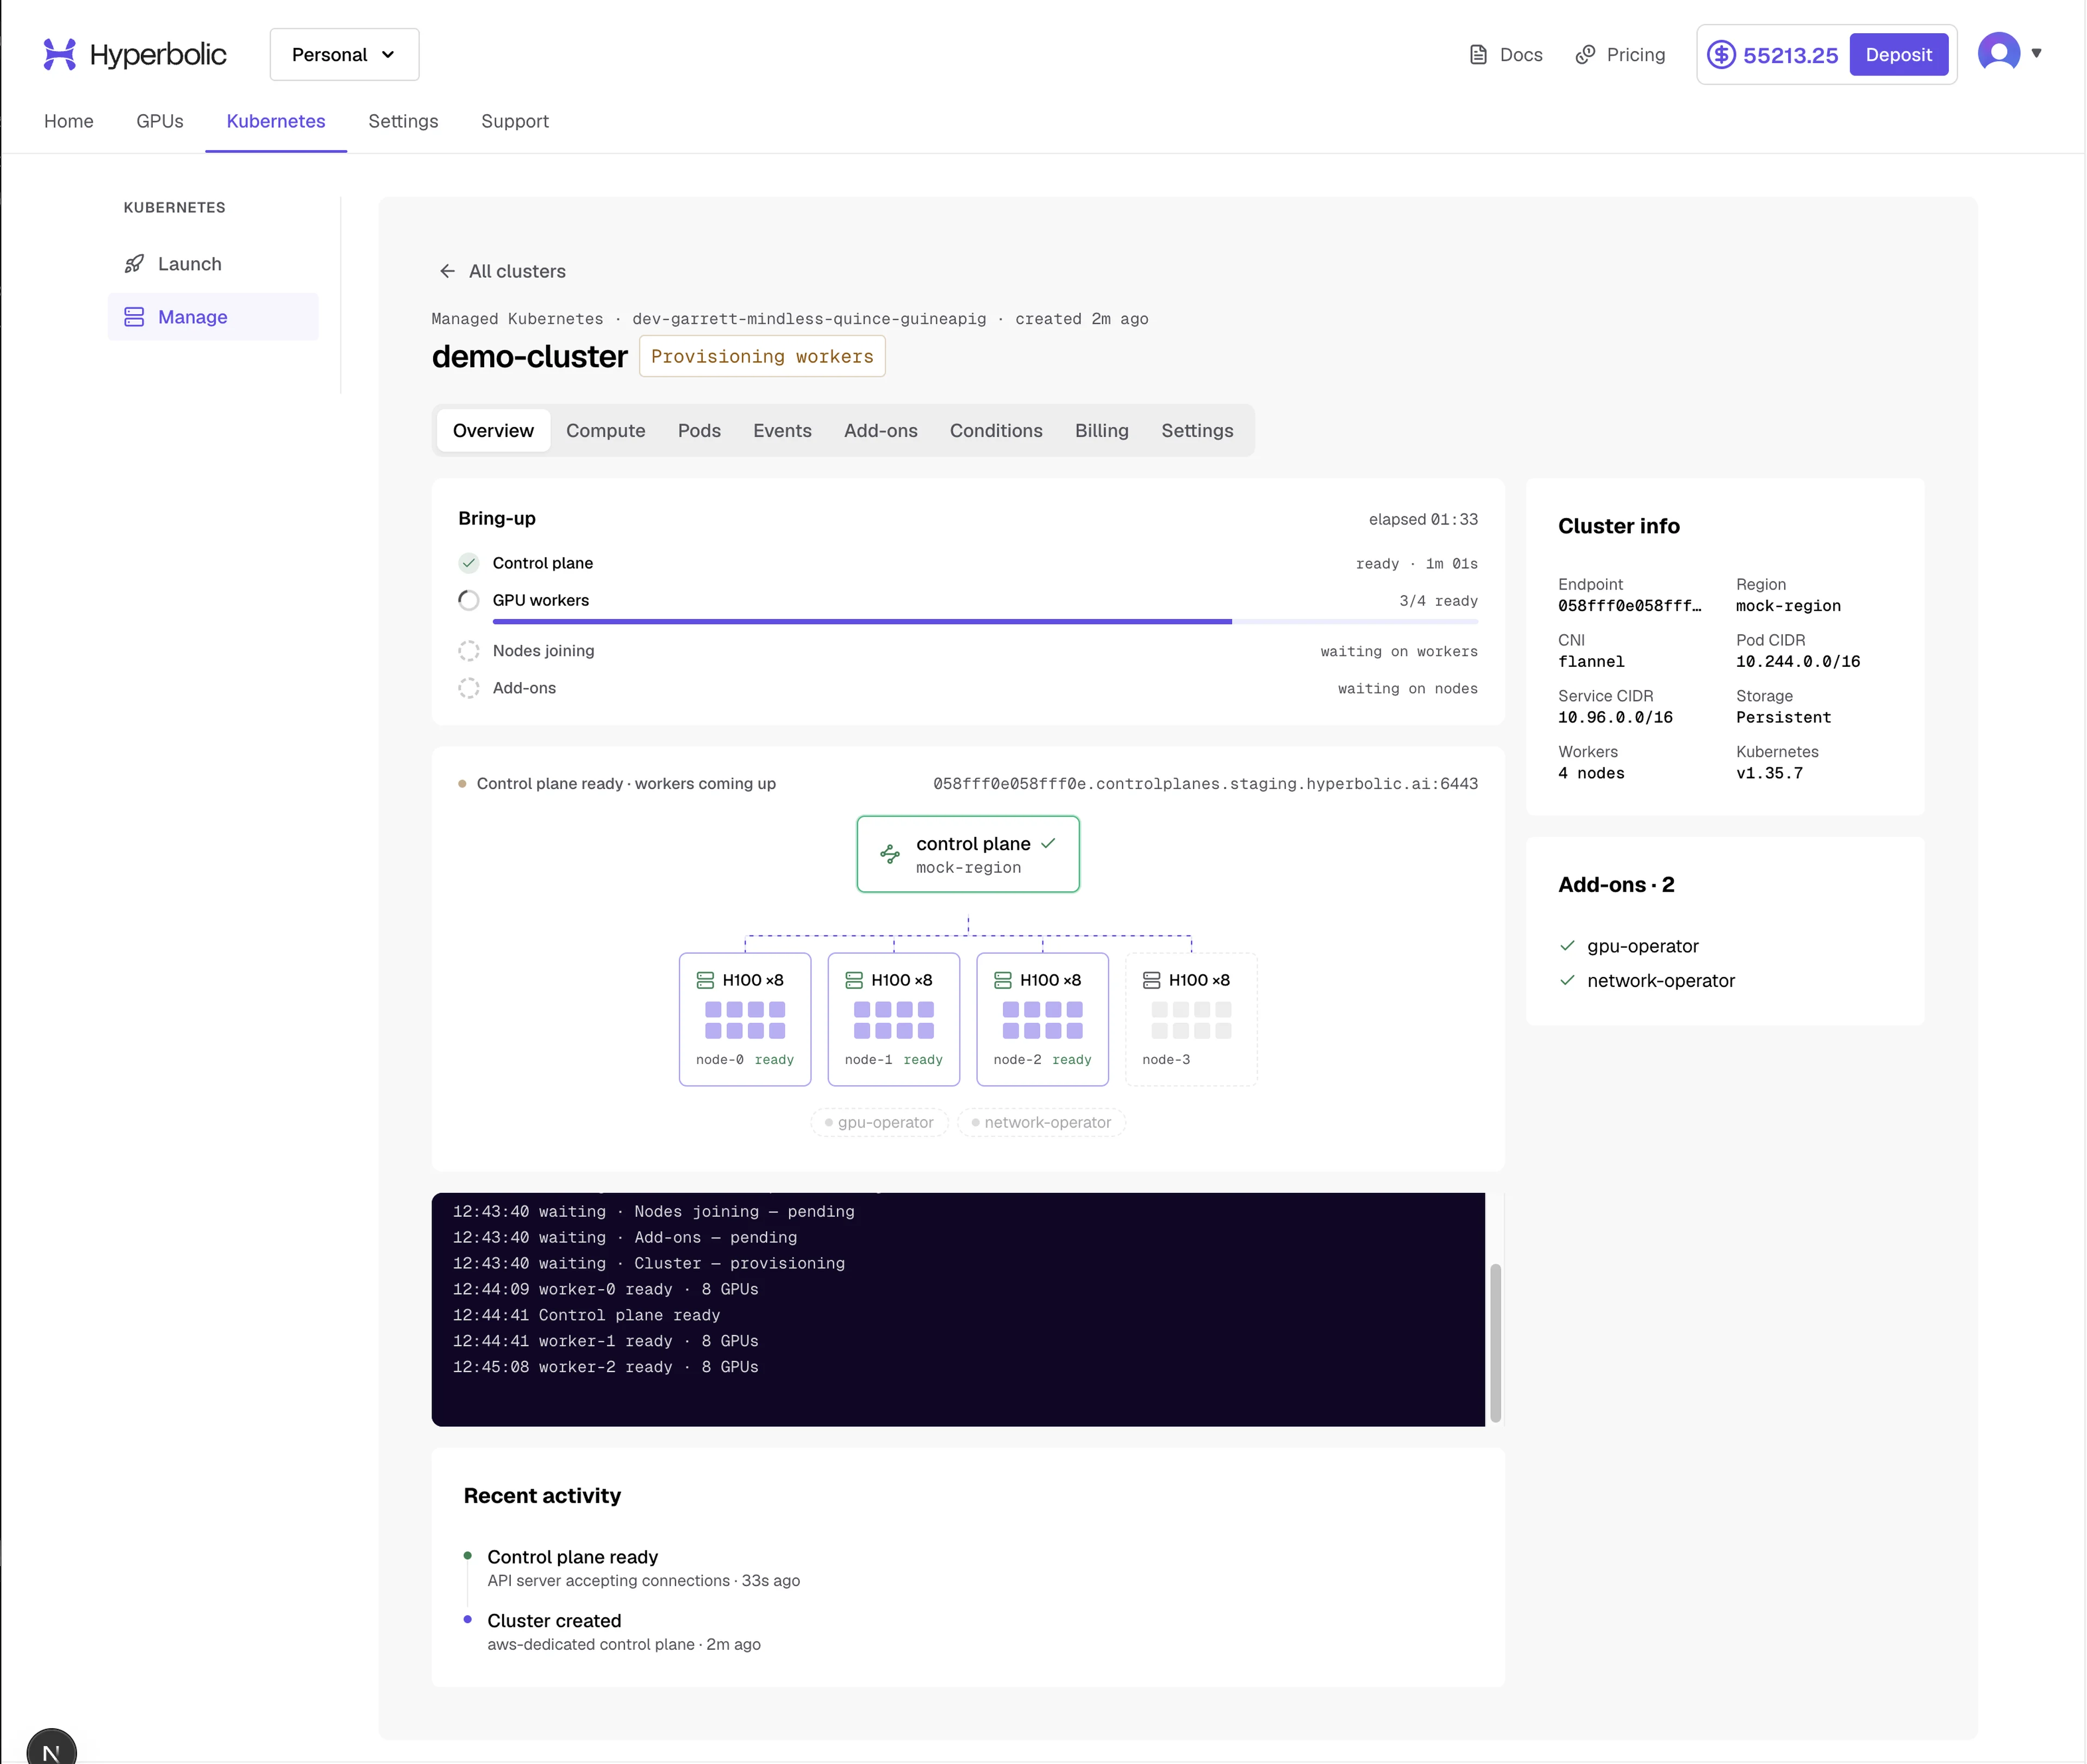
Provisioning in progress: the example has a ready control plane and three of four GPU workers ready; node joining and add-on setup are still pending in the progress tracker.
7. Review cluster health and access
Once provisioning completes, use Overview to review cluster health, ready-node counts, GPU utilization, workloads, and recent activity. Check that the workers needed for your workload are ready; the demo screenshot includes a partially provisioned node group, so its Running label alone does not indicate that every requested node is ready. Under Cluster info, select Download kubeconfig, then follow the connection instructions below.
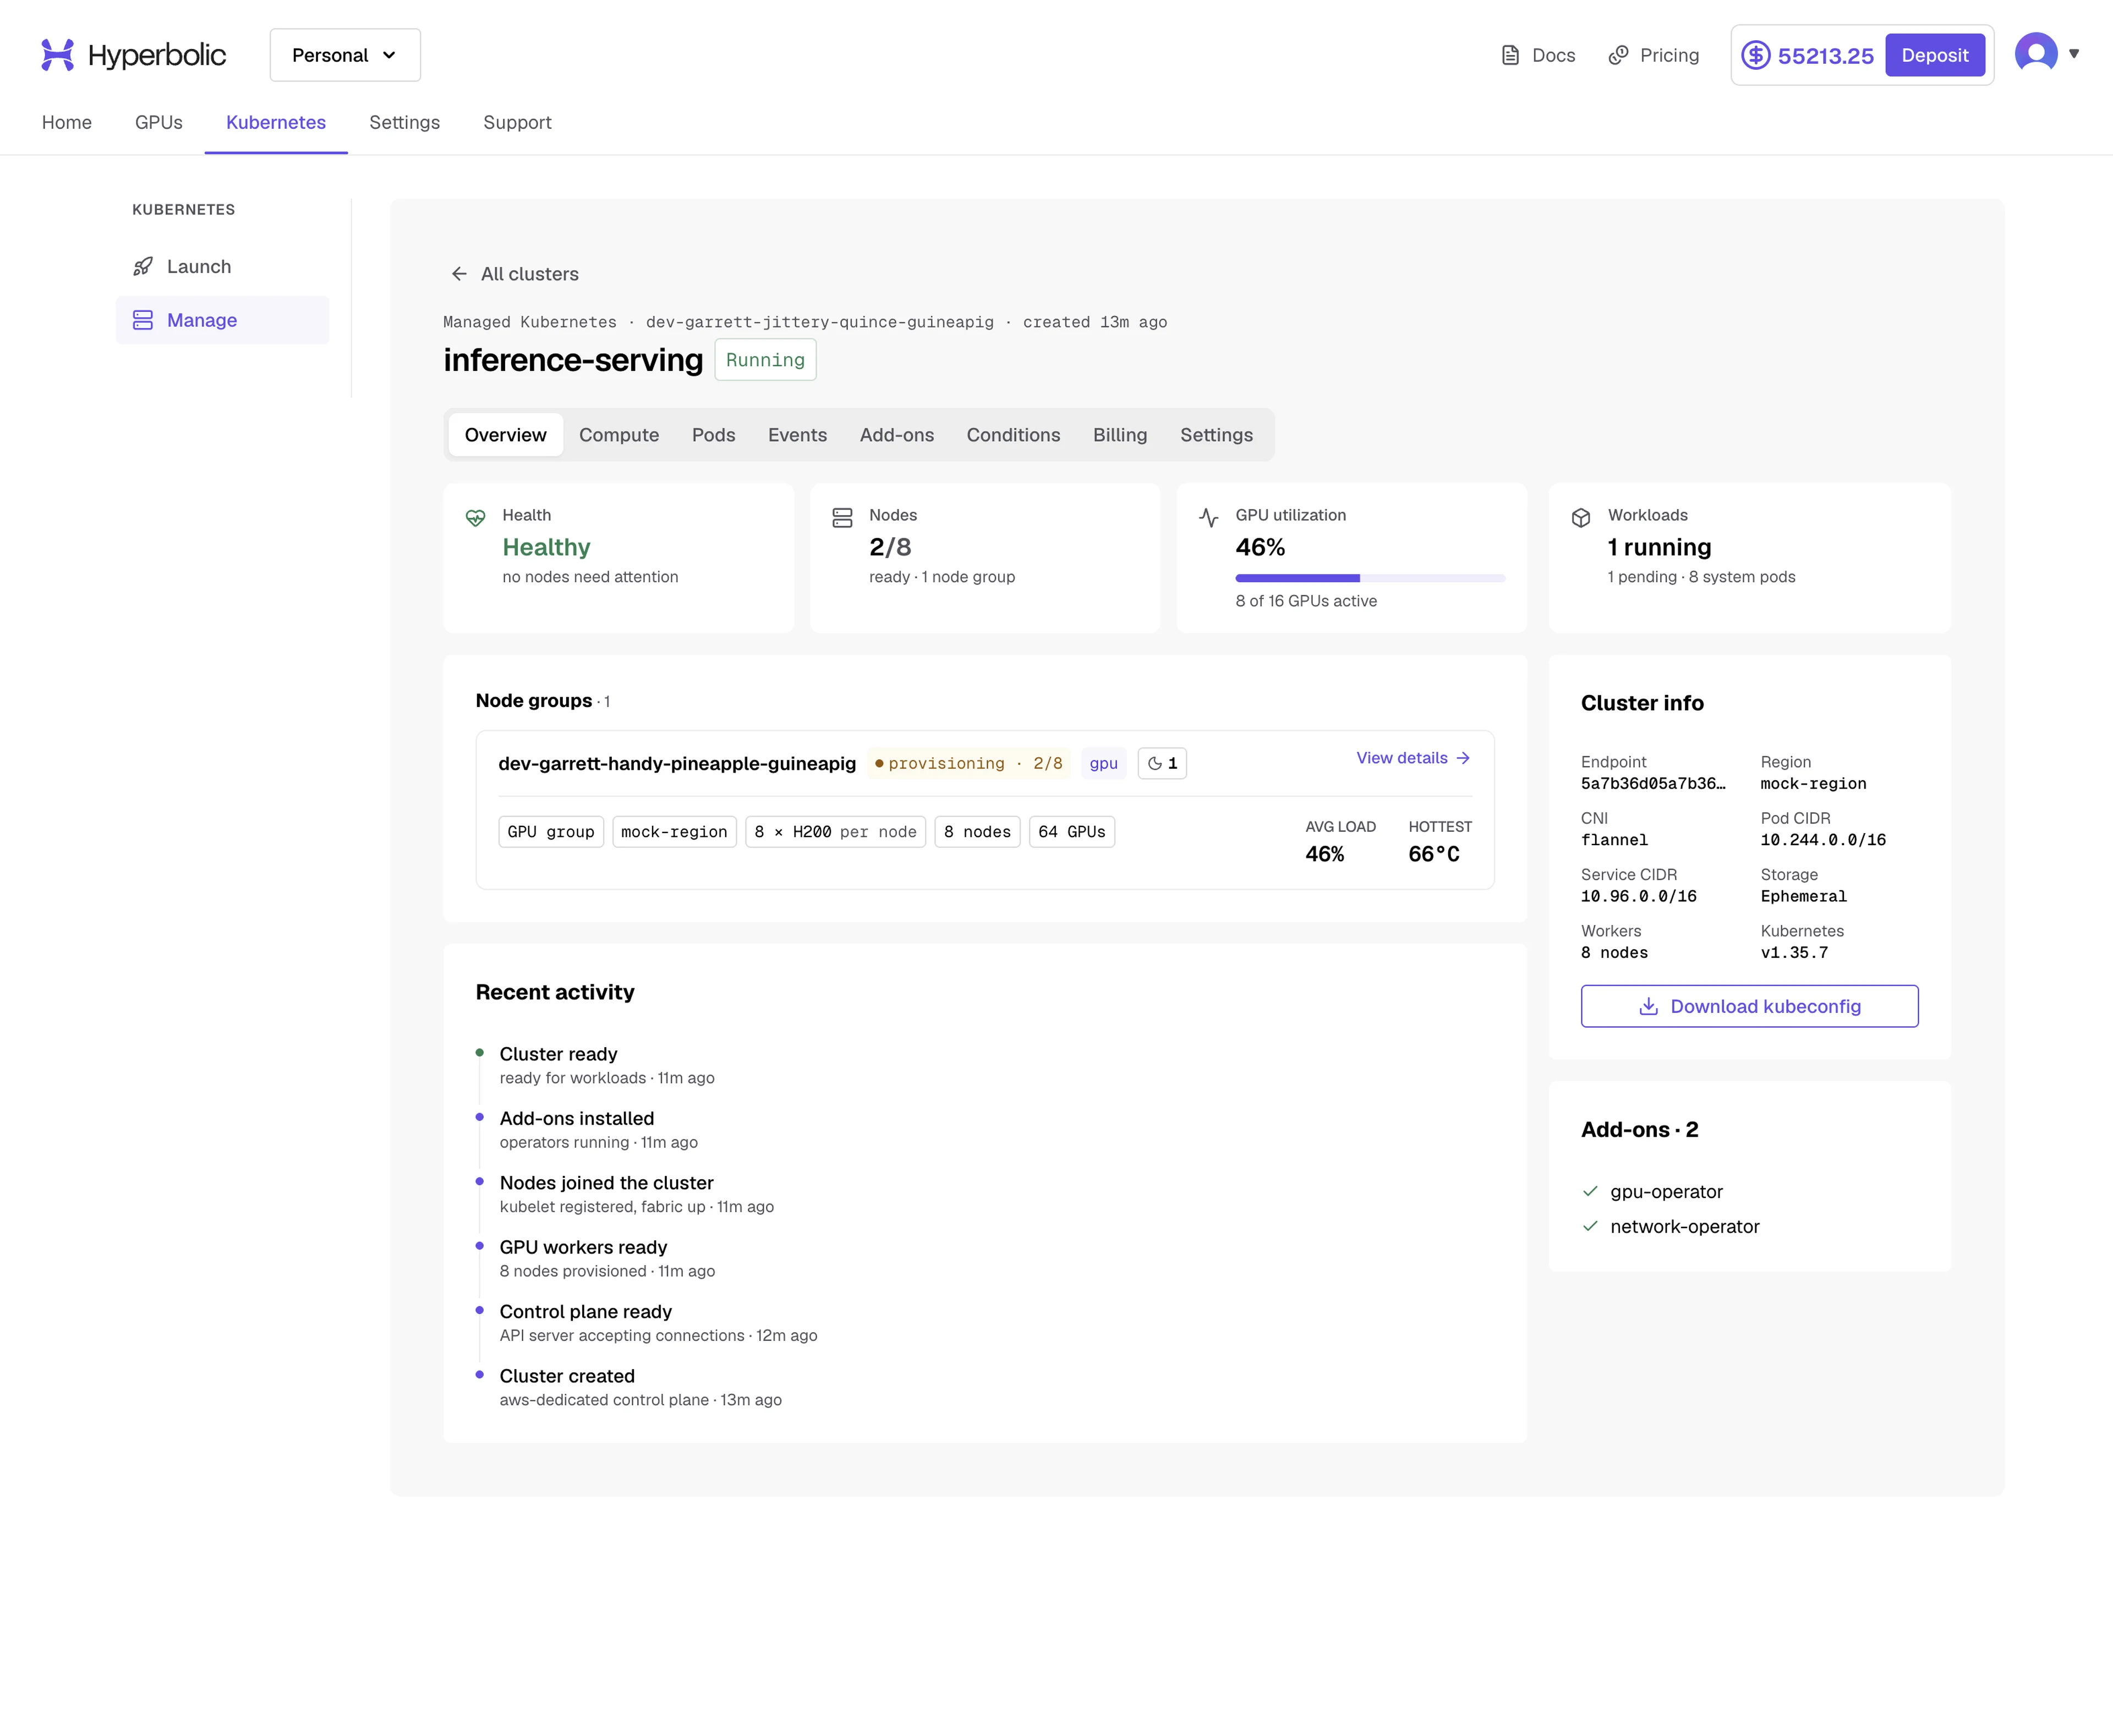
Review cluster health and worker readiness, then download kubeconfig from the Cluster info panel to connect.
8. Connect with kubeconfig and deploy your workload
When provisioning is complete, Hyperbolic exposes a control-plane endpoint for the cluster and makes its kubeconfig available to download from the dashboard. The kubeconfig contains the endpoint and certificate-based credentials needed to authenticate to the cluster API with cluster-admin access. Your team can configure namespaces, role-based access control (RBAC), network policies, and workloads.
Teams can then use kubectl, deployment pipelines, and other Kubernetes-compatible tooling against the cluster. The access model stays familiar to Kubernetes users while Hyperbolic handles the infrastructure work required to create and connect the control plane and GPU workers.
In a terminal with kubectl installed, set KUBECONFIG to the downloaded file's actual path; replace my-cluster.yaml below with its filename. Then list the nodes and confirm that the workers needed for your workload show Ready:
export KUBECONFIG=~/Downloads/my-cluster.yaml
kubectl get nodes -o wide
GPU worker nodes advertise nvidia.com/gpu capacity. Add a GPU request to the appropriate container in your workload manifest. The following is a container resource fragment, not a complete deployable manifest; it requests eight GPUs on a single worker:
resources:
  limits:
    nvidia.com/gpu: 8
Deploy your complete workload manifest with kubectl apply -f your-workload.yaml, replacing the filename with your own. Check pod status with kubectl get pods -A, or open the cluster's Pods tab. Once your workload is running, continue to Compute to inspect GPU activity.
9. Inspect node and GPU performance
After deploying your workload, return to the cluster in Manage and select Compute. Open the node group, then select a worker node to inspect its GPUs. This is a detail view of one server, rather than the cluster-wide overview.
The GPU cards show utilization, temperature, and power draw for each device. Node details show hardware and Kubernetes readiness, while the trend charts and Pods on this node section help you relate GPU activity to the workloads scheduled on that server.
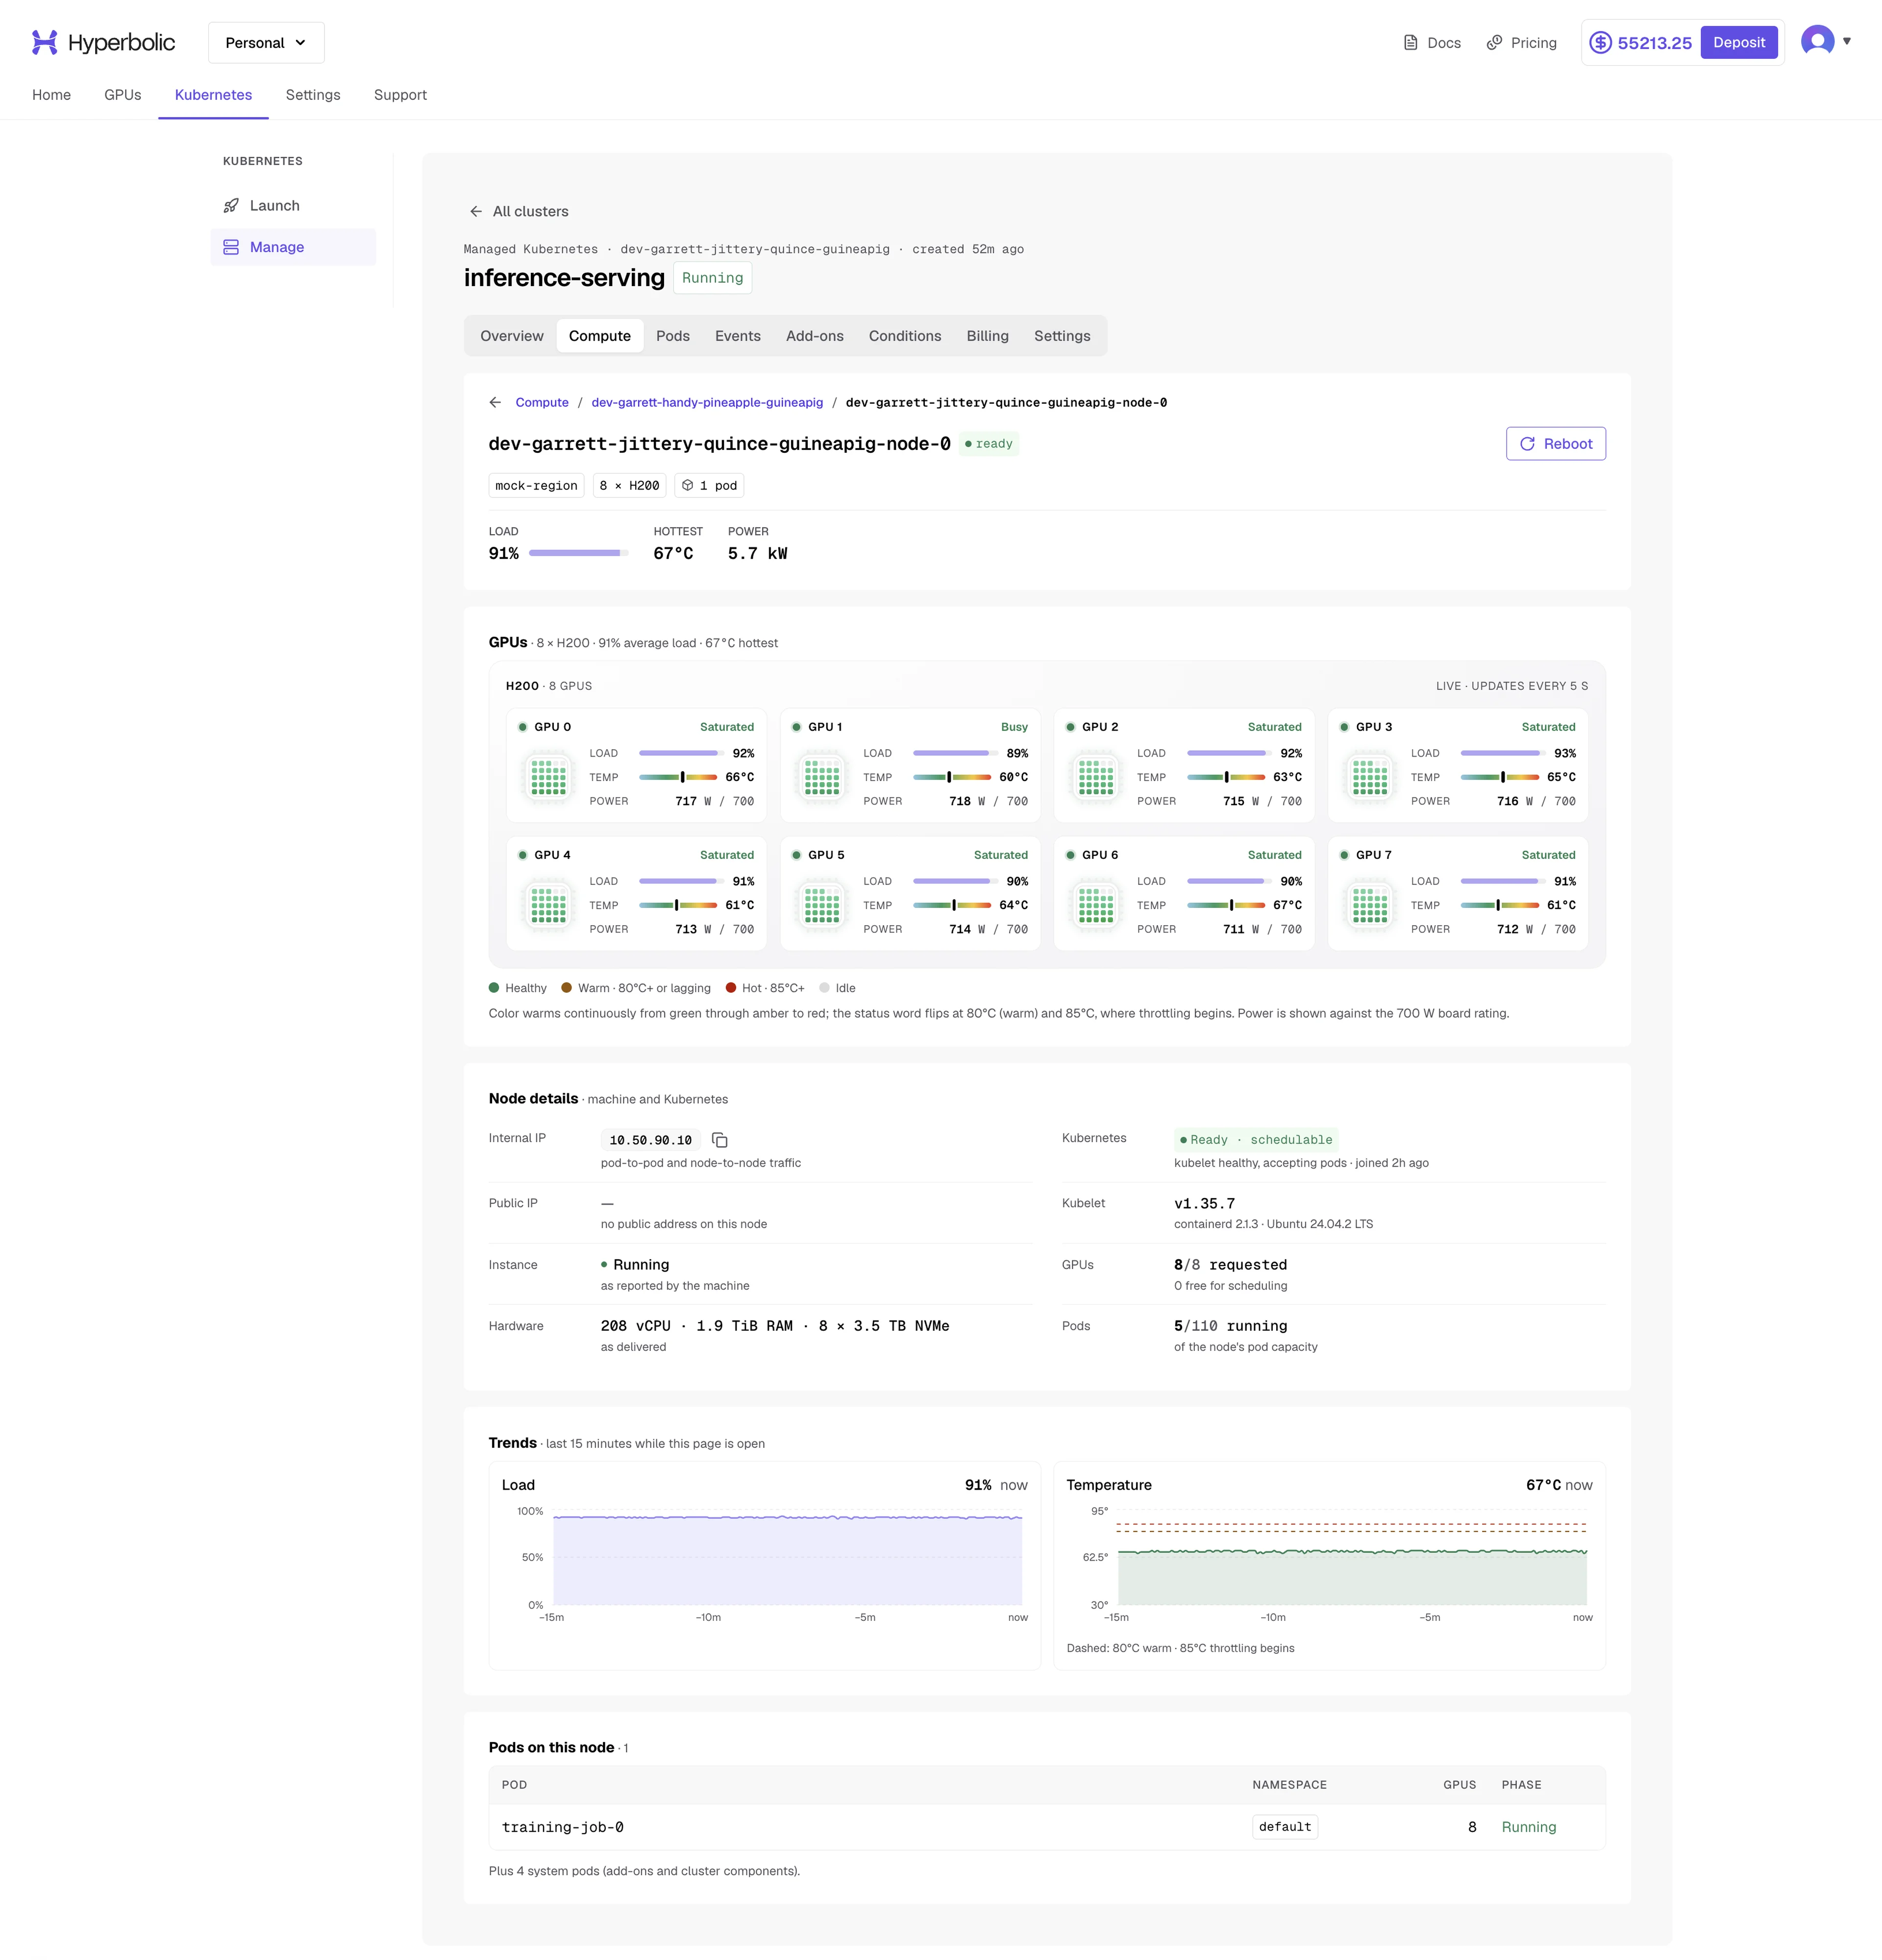
Inspect per-GPU metrics, node readiness, recent trends, and pods on an individual worker node.
Use the Compute breadcrumb to return to the node list, or select Overview to return to cluster-wide health and activity. For application-level monitoring, logging, and alerting, install Prometheus, Grafana, or the agents your team already uses.
Built for teams that already use Kubernetes
Managed Kubernetes removes the infrastructure assembly work around a GPU cluster. It does not replace Kubernetes itself or hide the cluster behind a proprietary workflow. Teams still use standard Kubernetes APIs and tools, control the workloads they deploy, and can change the add-ons and configuration inside their environment.
That balance matters for AI infrastructure teams. Hyperbolic provides the GPU capacity, control-plane provisioning, worker-node bootstrap, initial cluster components, and health visibility. The customer keeps the operational control required to run its own training, inference, and batch workloads.
Who manages what
Hyperbolic manages control-plane availability, node provisioning, GPU drivers, installation of cluster add-ons at bootstrap, and platform telemetry. You do not need to manage etcd or control-plane nodes.
Your team manages the workloads scheduled on the cluster, namespaces, RBAC, network policies, and application monitoring, logging, and alerting. Cluster-admin access lets you configure these components using standard Kubernetes tooling.
What is included in the beta
Managed Kubernetes is available in select regions with limited capacity during the beta. The current scope includes:
New instances only. Clusters are built from newly provisioned GPU instances. Existing rentals cannot yet be converted into managed Kubernetes clusters.
Launch-time sizing. Choose the worker-node count when you create the cluster. Node groups can be removed later, but in-place scaling is not supported in the beta.
Node-local storage. Pods can use node-local NVMe storage, but data does not survive node replacement. Keep training checkpoints and other data that must persist in your own object storage.
Regional capacity limits. GPU types and cluster sizes depend on available capacity in supported regions. Schedule a call for larger clusters or reserved-capacity requirements.
Get started with Managed Kubernetes
Managed Kubernetes for GPU workloads is available in beta in select regions. Sign in to the Hyperbolic console to create a cluster, or visit the Hyperbolic documentation for platform guidance.


